INPUT PORT: 01
>
eval_set: refund_qa · 240 examples
metric: rubric · pass-rate
AGENT ENGINE SANDBOX
OPTIMIZING PROMPT...
  .   .   ✶   .   .
    . ✶ ✶ ✶ .
  . ✶ ✶ ✶ ✶ .
    . ✶ ✶ ✶ .
  .   .   ✶   .   .
CPU: 4 · TOOLS: 5 MODE: apo-loop
OUTPUT EVAL
v3 -
v5 -
v7 -
Latest Writing
Thoughts on software development, AI, and building systems
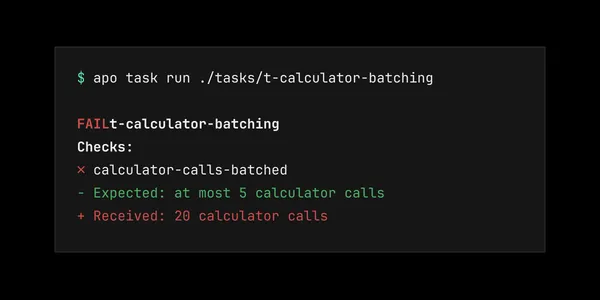
Defining Future Agent Capabilities with Evals
Most often when building evals, they are regression tests on the current system. But even greater use case is building it for frontier where you want your agents to go!
Evals Apo
Engineering Cheaper LLM Evals
Engineering solutions I have found when trying to implement a cheap way to do thousands of eval checks. From prompt structures and its cache points to the Jev and escalation modes for evals.
Evals Apo LLM-as-judge
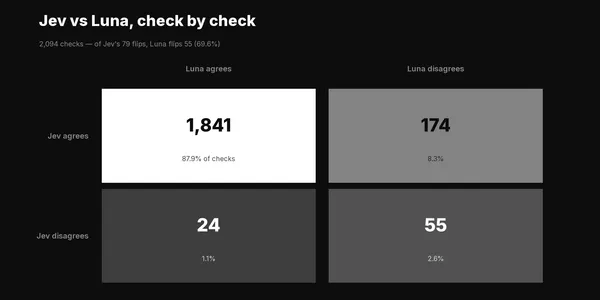
Jev vs OpenAI Decisions: 2,094 Real Eval Checks
Does it matter what System One model you should be using? On same tasks, how well do Jev and OpenAI's Decision API agree, and which one turns out to be stronger
Evals Apo Jev